Somewhere in your keyword file is a group of forty queries under one heading, and it will never become a published page. The heading came from a formula that matched words rather than results, so somebody shopping for a keyword clustering tool ended up filed beside a reader who has not met the term yet. Both now wait on one article that cannot serve either of them. You have probably opened that file, seen one large tidy block, and felt briefly organized. That feeling is the trap, and it survives until someone asks which page you are writing first. So here is the question I would put to you: if that block holds several different intentions, how many pages is your plan actually promising? The answer is already sitting in the search results, and it is not the number your file is showing you.
Somewhere in your keyword file is a group of forty queries under one heading, and it will never become a published page. The heading came from a formula that matched words rather than results, so somebody shopping for a keyword clustering tool ended up filed beside a reader who has not met the term yet. Both now wait on one article that cannot serve either of them. You have probably opened that file, seen one large tidy block, and felt briefly organized. That feeling is the trap, and it survives until someone asks which page you are writing first. So here is the question I would put to you: if that block holds several different intentions, how many pages is your plan actually promising? The answer is already sitting in the search results, and it is not the number your file is showing you.
I ran a second pass on those queries, each paired with its top ten organic results, and the two groupings disagree in ways worth seeing. The definition itself lives elsewhere on this site, so for the textbook version, keyword clustering is the short read. What follows is the demonstration, one list under two rules.
The one test that settles a keyword clustering call
Forget the wording. The only thing deciding whether two queries belong on the same page is whether the pages already ranking for them are the same pages.
Compare the top ten for two queries. Mostly the same URLs, and search engines have decided those queries want the same answer. Entirely different URLs, and they want different answers, however similar the two phrases look. You are not sorting keywords. You are reading a decision already made, ten results at a time, and copying it into a file structure.
That reading job is bigger than it sounds. An Ahrefs study of three million searches found the average number one ranking page also ranks in the top ten for close to 1,000 other relevant queries. A cluster is the normal shape of a ranking page, not a trick you apply to one. Get it wrong and the cost is a page you merge or kill six months later, plus the links you built into it by then.
The four grouping methods, ranked by how wrong they go
Four rules get used for this, and they fail at different volumes. The order runs from cheapest and worst to most expensive and most reliable.
Method | What it compares | Cost | Where it breaks |
|---|---|---|---|
Alphabetical or substring | The letters inside the query | Nothing, one formula | Collapses 40 of 44 queries into one bucket |
Word-count buckets | How many words a query has | Nothing, one formula | Matches on length, ignores meaning and intent |
Embedding similarity | How closely two queries read | A script and an API key | Blind to intent, merges a developer query with a marketer query |
Measured SERP overlap | The URLs two queries rank | A SERP data source, one pull per query | Over-splits genuine pairs, leaves a two-URL gray band |
The first row is the rule most lists are built on, and the test is literal: if one query's text contains another's, file them together. That is a SEARCH function in column D, and it is wrong in a way you cannot see until you try to write. The second row is the same mistake with a different trigger, since bucketing by word count files a three-word commercial query beside a three-word developer query.
The third row measures something, just not the right thing. SEOcrawl's write-up names it intent blindness: a model can place how to roast coffee next to buy roasted coffee because the two read alike, and one is a guide while the other is a purchase. Brightseotools logged the same error in September 2026, when best running shoes for men and best running shoes for flat feet were merged over a shared three-word prefix.
The fourth row compares search results instead of words, and it is what the rest of this page is about.
The SERP-overlap test, worked through on 44 real queries
Here is the setup, so you can rerun it. Every query in the database matching the clustering family, 44 after near-duplicates were pulled out, each paired with its top ten organic results for the United States on desktop. Then a count of how many of those ten URLs appear in both queries of a pair.

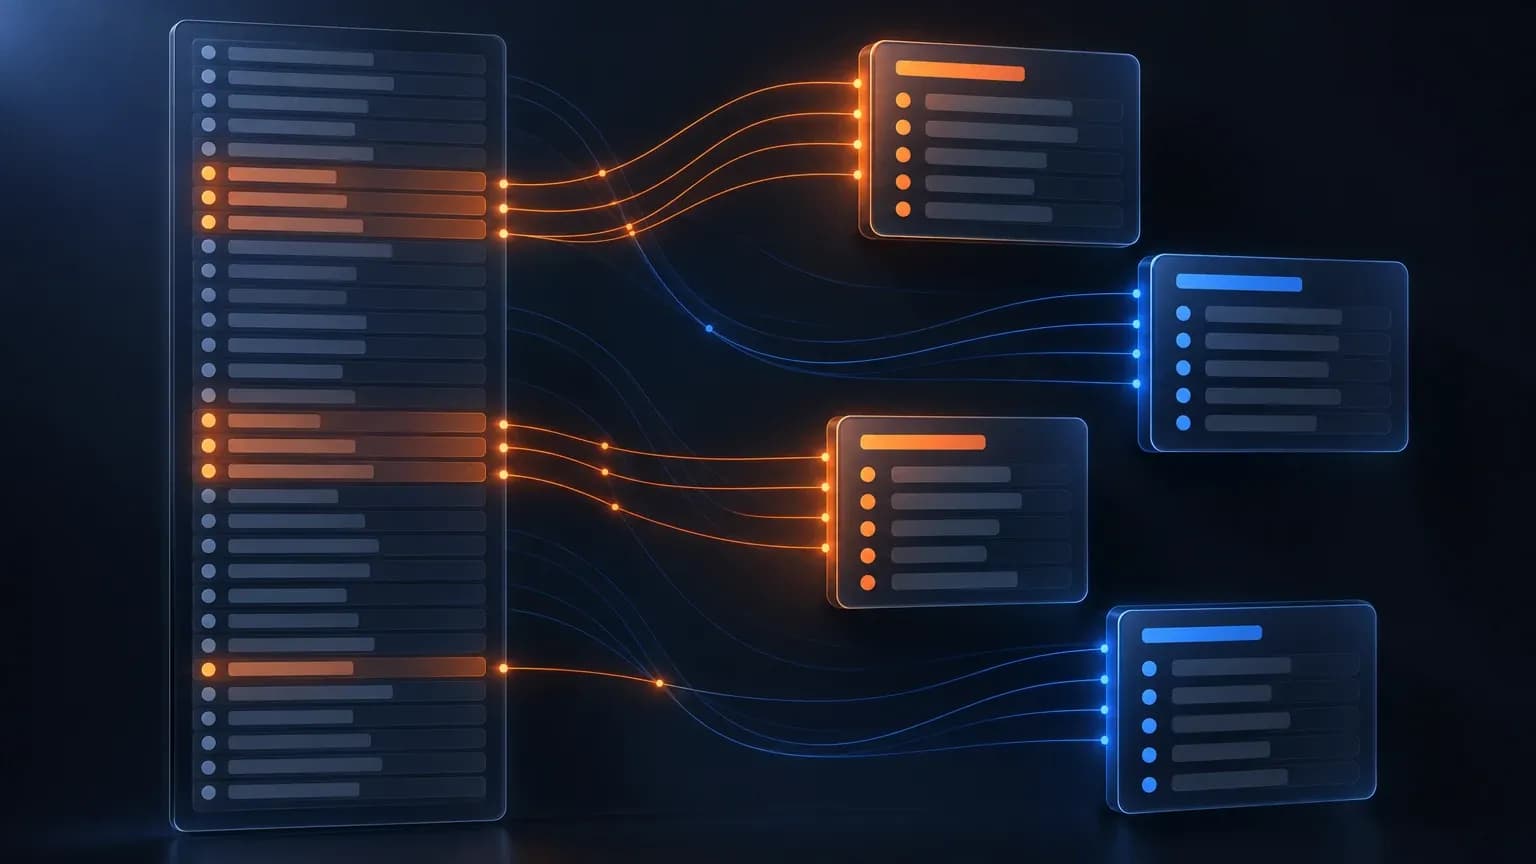
Apply the substring rule first. One bucket comes out, holding roughly 40 of the 44:
keyword clustering tool, keyword clustering tools, keyword clustering, what is keyword clustering, seo keyword clustering, best keyword clustering tools, keyword clustering examples, keyword clustering seo, semantic keyword clustering, keyword clustering python, keyword clustering nlp, keyword clustering machine learning, chatgpt keyword clustering, keyword clustering semrush, ahrefs keyword clustering, keyword grouping tool, keyword clustering meaning, free keyword clustering tool, and the brand long-tails hanging off the same string.
Read that as an editor and the problem is obvious. It holds a 720-search commercial head and a 480-search definitional head, which are a buyer and a beginner. It holds every competitor-branded variant, each wanting its own page or none. One page cannot carry that, and the combined volume makes it look like the page you should be writing.
Now the same list, measured. Eight pairs, with the actual shared-URL counts:
Pair | Shared URLs in the top 10 | What it means |
|---|---|---|
| 2 | One query, and the count alone would split them |
| 2 | One definitional and method page |
| 2 | Both tool-shopping, a merge candidate |
| 1 | Grouping pulls its own set of free utilities |
| 0 | Two audiences, two pages |
| 0 | Free-tool shoppers, a page we chose not to write |
| 0 | The content-planning bridge, a separate page |
| 0 | A different concept with its own results |
That table is the whole argument. The overlap rule works as a veto: it refuses to merge the Python query with the semantic one, refuses the cannibalization pairing, refuses the topic-cluster bridge, and in each case the string rule had already merged them.
Then it fails twice, on pairs no human would question. keyword clustering tool and keyword clustering tools are one query, and they score 2. free keyword clustering tool and keyword clustering tool free are also one need, and reversing the word order returned top tens with zero overlapping URLs, because different pages got served to each. Strict overlap splits both and gives you two thin pages instead of one good one.
So the usable rule has three zones:
- 0 or 1 shared URLs: different pages. A reliable stop sign.
- 3 or more out of ten: the same page. Wikipedia's entry on keyword clustering describes this number as a dial rather than a default, and that is the right way to think about it. Three or four out of ten is the common setting, convention rather than law.
- 2 shared URLs: the zone where the tool cannot help. Open both result pages and ask whether the ranking URLs answer the same question. Both sets tool pages, merge. One set tool pages and one explainer, split.
Palvdm.com's guidance is to review manually any cluster sitting at the threshold before you commit to merging. That is not a gap in the software, it is the shape of the problem.
One correction no page I found states, and it cost me a wrong call before I caught it. Count URLs, never domains. Two threads from the same forum appeared in two different result sets in these pulls, and counting the domain once made an unrelated pair look closer than it was.
The two failure cases, side by side
Both come out of the same list, and they run in opposite directions.
One "cluster" that is really two pages. The substring pass files keyword clustering tool with what is keyword clustering. Measured, those two result sets barely touch: the commercial one is a row of vendor pages, and the definitional one is where an academic figure page and an astronomy forum thread still hold positions five, eight and ten. Two questions, two answers, two pages. A single article serving both is the half-answer problem.
Two "clusters" that must be one page. keyword clustering tool and keyword clustering tools share two URLs, below any sensible threshold. A tool splitting on a strict three-URL rule separates them, and now two of your pages compete for one query. That is cannibalization manufactured by the clustering step, before a word gets written.
Both failures come from one tool applying one threshold. Deciding between them is a judgment the data can inform but not make.
Clustering 500 keywords by hand: where the spreadsheet collapses
The manual path is real and it works. Export the list, pull the top ten results per query, build a grid of shared URLs, walk down it. The problem is arithmetic.
The published numbers agree with each other. Nightwatch puts a 200-query list at 8 to 10 hours of manual clustering and names the reason: when you are tired you cluster by word similarity instead of intent, and you never notice. Rankdots places the average at 3 to 5 hours per client in each research cycle.
Scale that. At 500 queries the lookups alone are 500 separate pulls, and you have not compared anything yet. The spreadsheet is not the bottleneck because it is slow. It is the bottleneck because it offers no defense against your own tiredness, and the failure it produces, a merged bucket, looks exactly like success when you open the file the next morning.
What a keyword clustering tool actually automates
Strip the marketing away and the category does three jobs.
- Fetch. Pull the top ten organic results for each query from a live search source.
- Compare. Measure URL overlap between every pair in the set.
- Group. Merge the pairs above your threshold and label each group with its dominant intent.
The differences between products are mostly about which of the three they do. Some run all three and hand you labeled clusters. Some do compare and group only and expect you to bring the SERP data. A third group skips fetch and compares words instead of results, which puts them back on the third row of the method table.
Be careful with vendor claims here, including the flattering ones. One vendor publishes an accuracy test comparing SERP-based tools to semantic ones and scores its preferred method far higher, which is a company grading its own homework and should be read as a claim rather than a result. Pricing seen on listing pages in October 2026 started at $58 a month on one product and $9.99 on another, so check the live pages before you budget.
What the category does not automate is the part that decides the quality of your output. The threshold for your site depends on your authority: lower-authority sites should cluster harder into tighter, more specific pages, while established sites can consolidate. Every borderline pair still needs eyes. And Nightwatch flags the case no overlap number can settle, two queries with near-identical results and clearly different commercial value.
Cluster to page map: pillar, spoke, and what you deliberately skip
Clustering is not the deliverable. The page map is. Once the 44 queries are grouped by measured overlap, the output stops being a keyword table and becomes a content plan.

Cluster, one page each | Head term | Intent | The call |
|---|---|---|---|
The method | | Commercial | This page, the pillar of the set |
The definition | | Informational | Lives on the glossary entry, not as a second post |
Competitor arms | | Informational | Wait until each earns enough volume to carry a page |
Tool-brand arm | | Informational | Not yet, these only make sense once someone searches the brand alone |
Technical arm | | Informational | Not writing, wrong audience for this site |
Free-tool arm | | Informational | Deliberately skipped, thin intent and no fit |
Two things matter more than the rows. The first is that the skipped rows are a decision, not an oversight: writing the free-tool arm would be easy, and it would pull the whole cluster toward an audience that buys nothing. The second is the ordering. The pillar goes first, because it carries the commercial head term and every spoke links back to it.
When that pillar needs research underneath it, the heavy lifting is keyword research. Once the cluster runs, the parts worth automating are the recurring checks and the reporting, which automate SEO reporting and SEO automation cover. If your clusters point at technical pages rather than editorial ones, the same map drives a technical SEO audit. And when you are picking the tools around this workflow, we keep a list of the best SEO tools and the marketing analytics tools that show whether a cluster earns its pages. Then re-pull the overlap every 3 to 6 months, because results drift.
Where the 44-query run leaves you
Two rules, one list, and the gap between them is the job. The substring pass gave you a bucket of 40 queries and no page you could write. The overlap pass gave you six rows, plus a two-URL band no product will resolve for you.
If you take one number away, take the threshold: 3 or more shared URLs out of ten means one page, 0 or 1 means two, and 2 means open both and look. That line catches most of the merges that quietly turn into cannibalization six months later.
Running this by hand works right up until it does not, and the honest fix is to automate the fetching and the comparing while keeping the threshold calls with a person.
The question worth sitting with is not which tool you pick. It is which of your existing pages was written against a cluster that was never really one page, and how long it has been competing with itself.
Frequently Asked Questions
Can I cluster keywords in a spreadsheet?
Yes, up to roughly 150 queries. One row per query, one column per shared URL, and a count of the overlap. What breaks at volume is not the formula, it is the person: 500 sets of top-ten results is 500 lookups before any comparison starts, and the fatigue failure mode is clustering by word similarity while believing you are clustering by intent.
Do I need a paid keyword clustering tool?
Only if the fetching is what stops you. If you supply the SERP data yourself, the compare and group steps run on formulas for nothing. Buy when the lookups are the bottleneck, or when the same run has to repeat monthly without a person in it. Then check what you are buying: a product that skips fetch and compares words has moved you back to embedding similarity.
Is keyword clustering the same as keyword research?
No, and the two get merged constantly in how teams talk about them. Research produces the list, and the list is unlimited. Clustering decides how many pages that list becomes, which is a much smaller number and the only one that reaches your content calendar. That is how a good list and a bad plan coexist for months without anyone noticing.
How many keywords should be in a cluster?
However many the search results put there, usually fewer than people expect. A cluster is not a bucket you fill to a target size, it is the set of queries already resolving to one page, so six well-matched queries beat thirty that share a phrase. The commercial cluster in this run settled at eight terms once brand variants and developer terms were peeled off.
What do I do with a keyword that fits no cluster?
Leave it out of the plan and leave it in the file. A query with no overlap against anything on your list is not automatically an opportunity, it is usually a different topic wearing similar words, and `keyword clustering python` is the example from this set.
Put your own list through it
Allable runs the whole loop in one place: the queries come in, the clusters come out mapped to pages, and the plan moves from a spreadsheet into a schedule without a rebuild in between. Put your own 44-query list through it on a 7-day trial at studio.allable.ai.